MLOps & model lifecycle management
- Model versioning, testing, and validation
- CI/CD pipelines for machine learning
- Automated model deployment
- Model registry and artifact management
- Integration with MLflow, Kubeflow, SageMaker Pipelines
We operationalize AI and data systems to ensure reliability, scalability, and continuous improvement. From model lifecycle management to drift detection, automated retraining, and continuous monitoring.
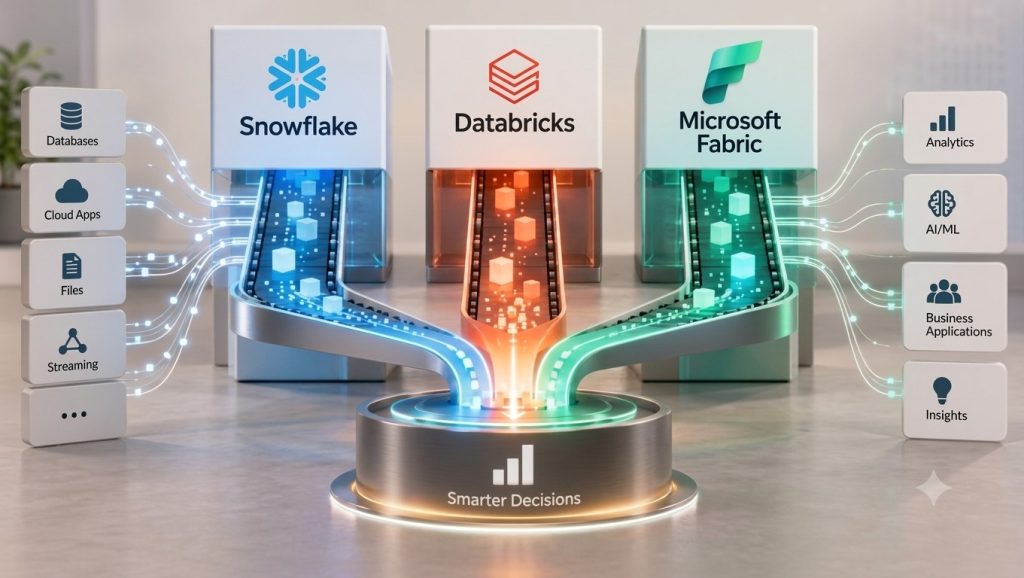
We work across all major MLOps and DataOps platforms, and we’re architecture-led, not platform-led. We recommend what’s best for your business.

Open-source MLOps platform for model lifecycle management, experiment tracking, and model registry. Integration with Databricks, Azure ML, and SageMaker.

CI/CD pipelines for ML and data. Integration with Azure ML, Databricks, and Fabric. Automated testing, deployment, and governance.

Kubernetes-native ML workflows. Model training, deployment, and monitoring at scale. Integration with AKS, EKS, and GKE.

AWS-native MLOps with SageMaker Pipelines. Model building, training, deployment, and monitoring. Integration with AWS data and security services.
GCP-native MLOps with Vertex AI Pipelines. End-to-end model lifecycle on Google Cloud. Integration with BigQuery and Dataflow.
Monitoring and observability for ML and data systems. Custom dashboards, alerting, and performance tracking. Integration with Kubernetes and cloud platforms.
We don’t build prototypes. We build production-grade MLOps pipelines with scalability, reliability, and governance baked in from the start.
Models degrade over time. We build MLOps pipelines that monitor, detect drift, and automatically retrain, ensuring your AI gets better, not worse.
From data pipelines to model deployment to monitoring. We automate the entire lifecycle so your teams can focus on innovation, not operations.
We recommend what’s best for your business, not what fills partner quotas. Our decisions are driven by your infrastructure, use cases, and goals.
Faster time-to-production for AI models.
Reduced model failure and degradation through continuous monitoring.
Continuous optimization of AI systems.
Automated retraining and improvement cycles.
Reduced manual intervention in ML operations.
From experiment to production with full automation and governance. Let’s build MLOps and DataOps pipelines that keep your AI reliable, scalable, and continuously improving.